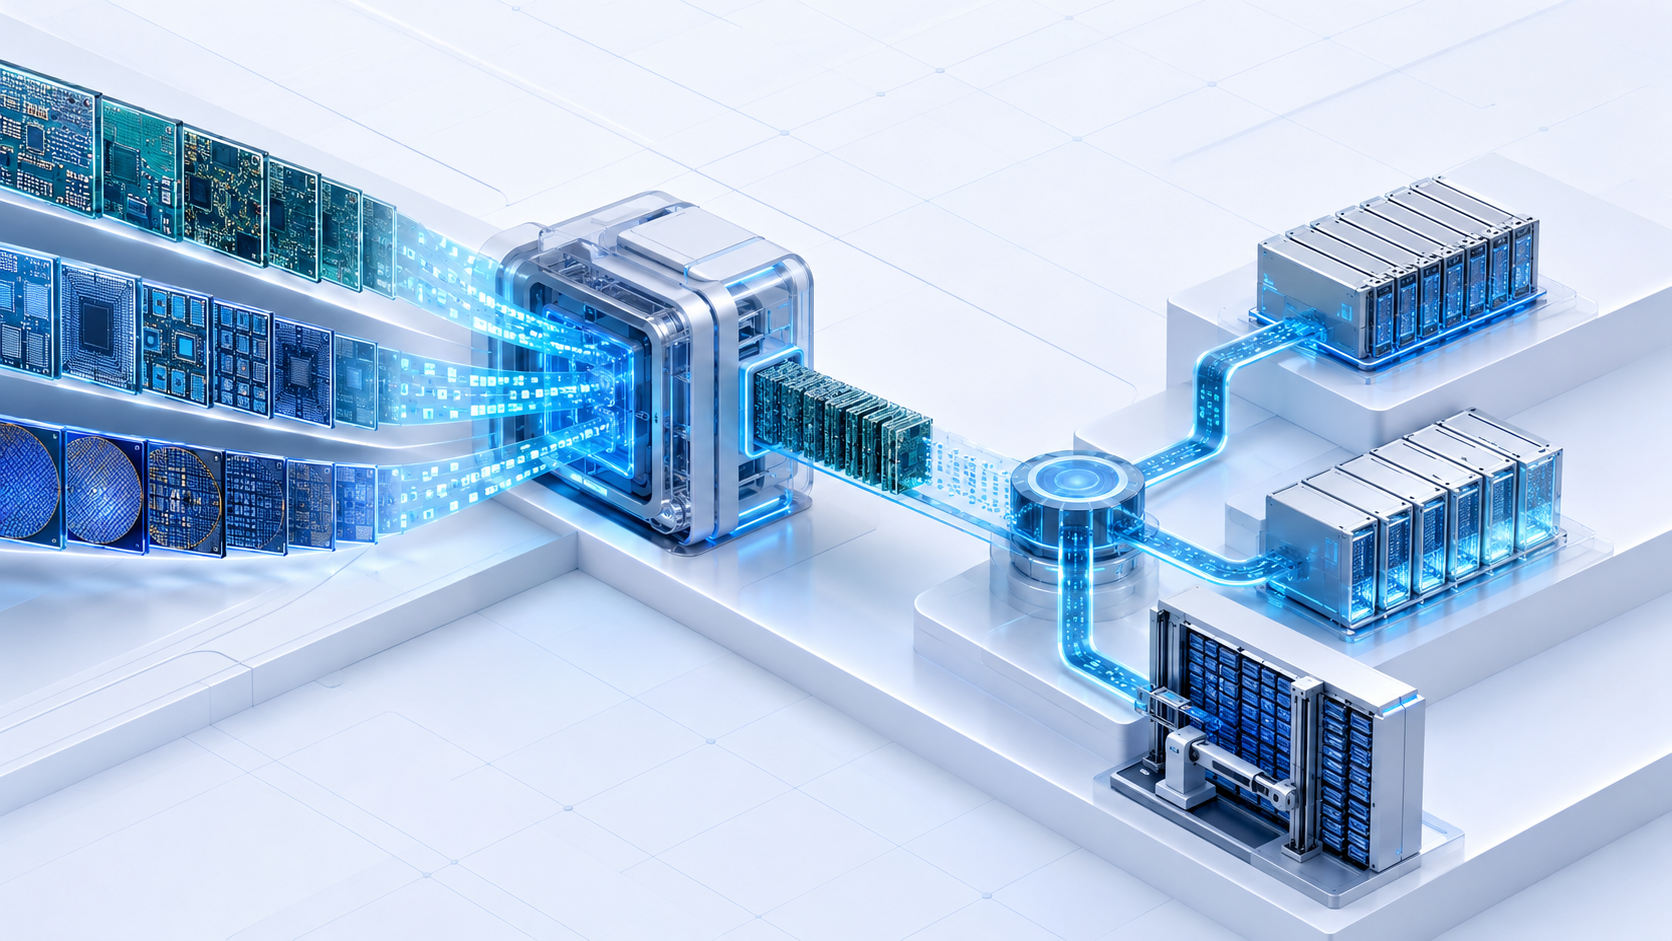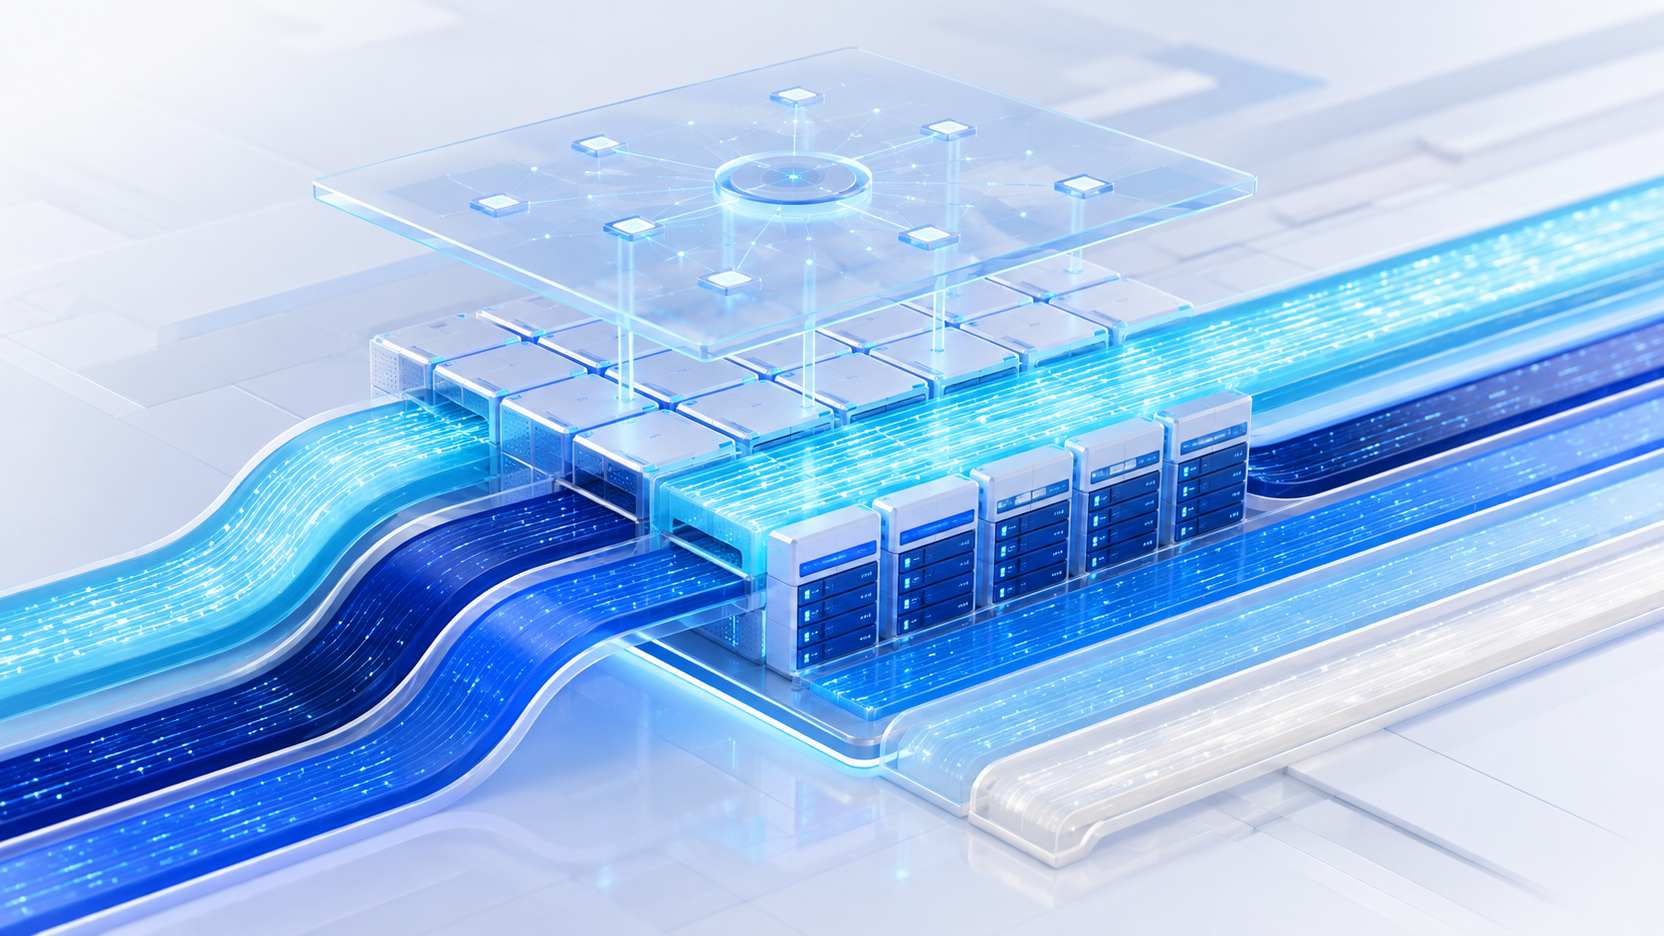
AI and manufacturing workloads often combine a few very large objects with enormous populations of small files. Traditional metadata designs can become the limiting factor long before raw capacity is exhausted.
Small files change the performance equation
Opening, listing, tagging, and locating a file may consume more system work than transferring its contents. Centralized metadata services can therefore cap throughput as file populations rise.
Scale metadata with data
A distributed key-value design spreads metadata operations and grows with the cluster. Capacity and namespace performance can expand together instead of depending on a fixed controller.
Beyond file-system mechanics
For IDM and MOS workflows, metadata also carries lot, wafer, equipment, time, and policy context. That makes the namespace useful to quality analytics and AI dataset construction, not only storage operations.