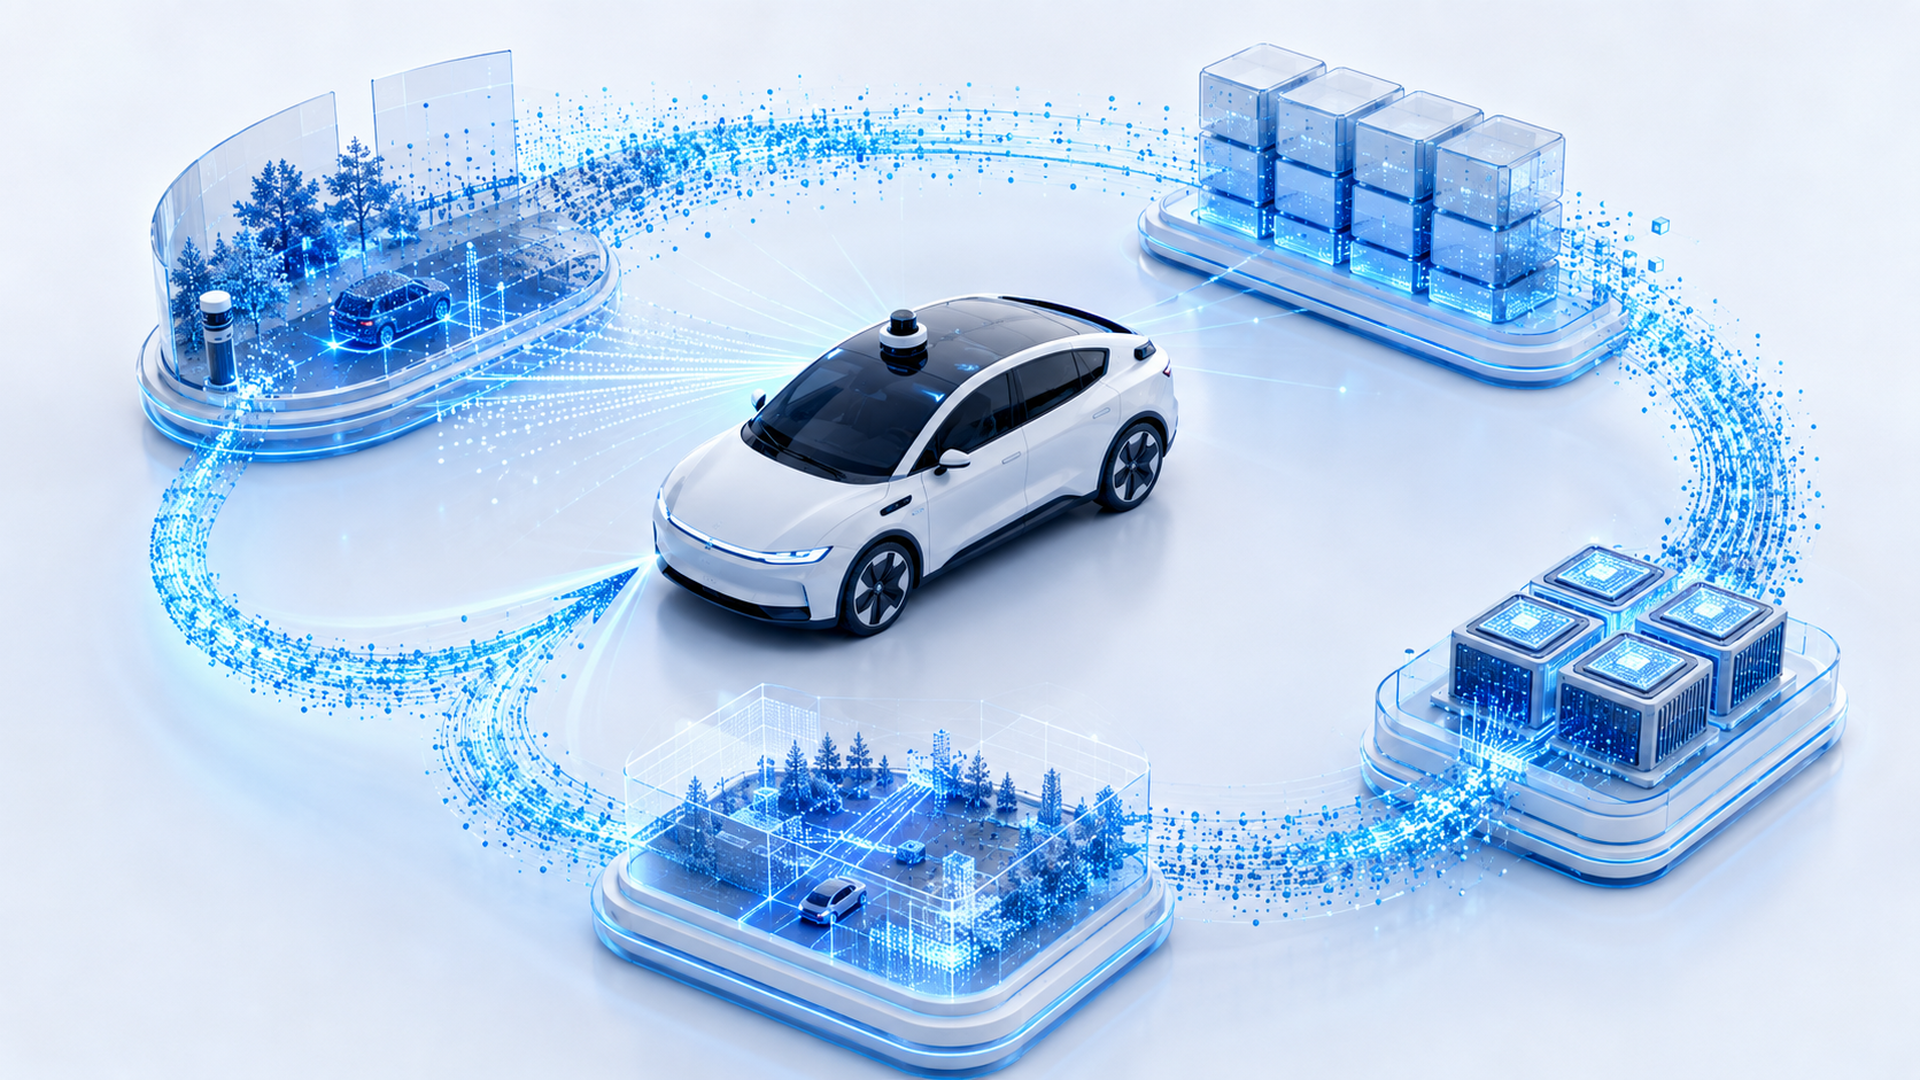
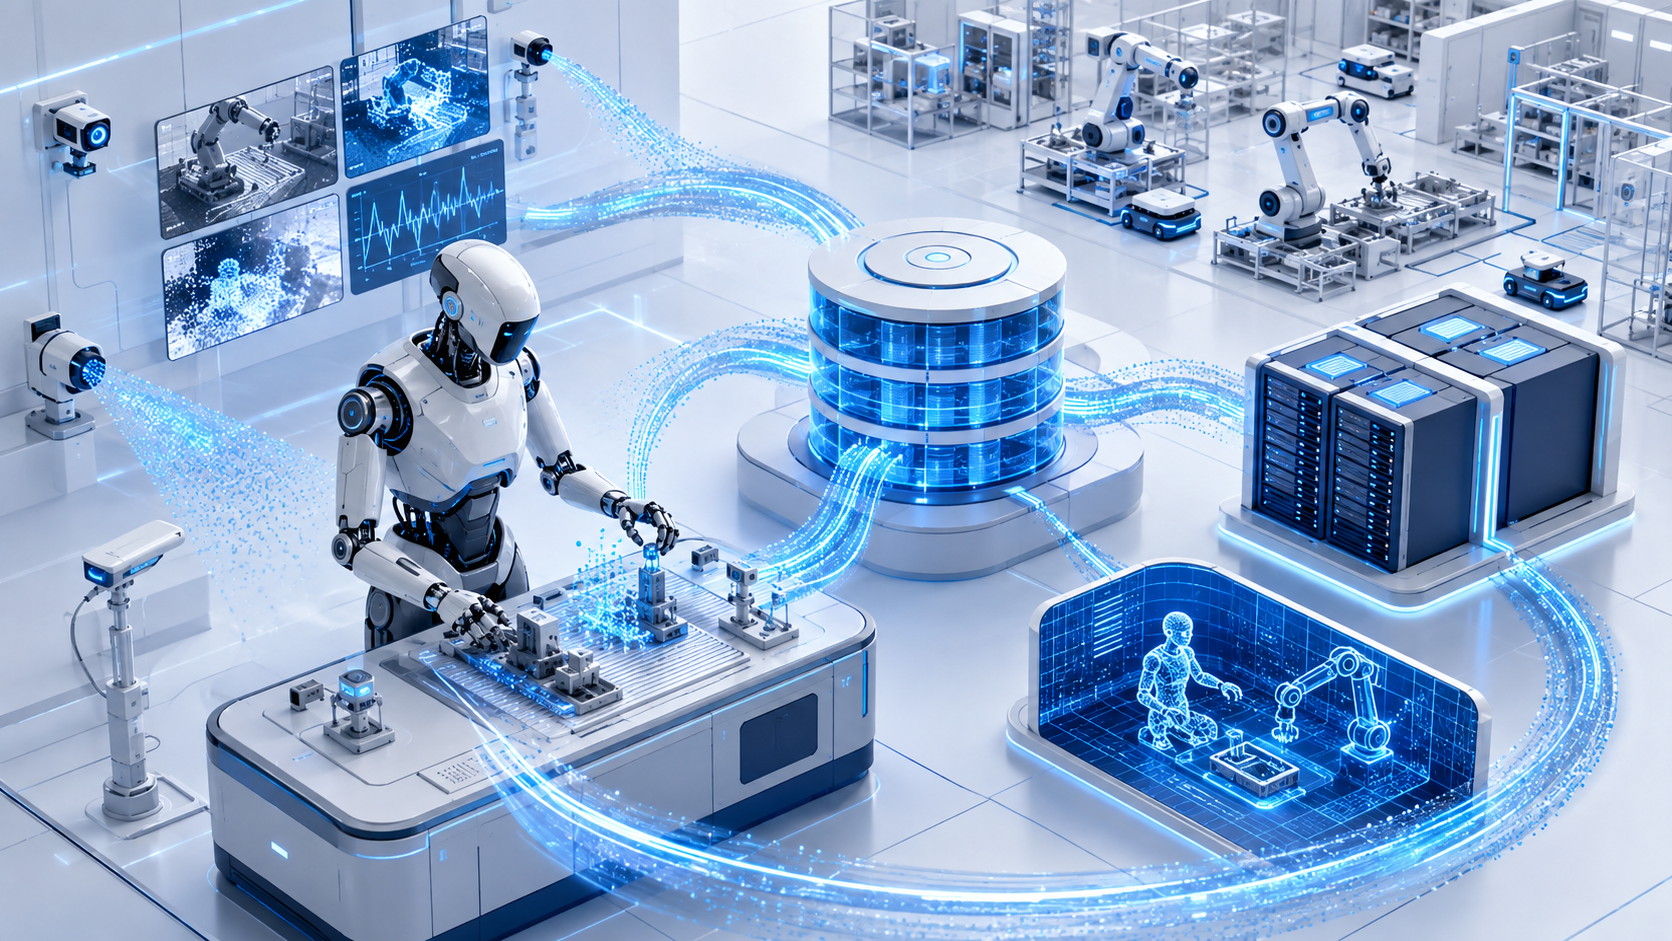
A capable robot improves through repeated interaction with the physical world. That creates a compounding data problem: more deployments produce more multimodal evidence, which creates more training and simulation work.
Learning systems create compounding data
Video, point clouds, telemetry, labels, synthetic scenarios, checkpoints, and evaluation results grow together. Managing each type in a separate silo makes datasets harder to reproduce and reuse.
The infrastructure must stay out of the way
Robotics pipelines need both large sequential streams and huge populations of small files. Distributed metadata, parallel access, and multi-protocol support keep storage from becoming the bottleneck.
Governed reuse accelerates iteration
When raw and derived data share traceable context, teams can rebuild training sets, compare model versions, and retain valuable long-tail scenarios without uncontrolled duplication.